
Free Data Lakehouse for a Cloud Native World

Deploy Apache Spark on Kubernetes in minutes with your fully managed platform.

$curl -fsSL https://get.ilum.cloud/cli | bash
Enjoy all our features at no cost. A unified data lakehouse platform for data analytics and AI. One platform to manage all your data workflows – faster, easier, and free.
Ilum Data Lakehouse Dashboard Screenshots showing Spark Cluster Management
Data Exploration

Data Exploration

Multi-Cluster Management

Multi-Cluster Management

Automated Data Lineage

Automated Data Lineage

Companies using ilum

Over 200 data teams already unlocking insights with Ilum's

Managed Data Lakehouse for Any Deployment

Unlock the flexibility of Ilum’s free managed data lakehouse platform, designed to be deployed across on-premise, cloud, or hybrid environments. Our modern data lakehouse architecture combines the flexibility of data lakes with the speed of warehouses – Ilum gives you both, offering a complete Spark on Kubernetes solution without the cost.

The Power to Customize Your Data Platform

Ilum empowers you to choose the tools that fit your workflow best, whether it’s Delta Lake, Apache Iceberg, or Apache Hudi.

You’re not locked into a single BI tool or Notebook. Connect with PowerBI, Tableau, or use our built-in modules like Superset.

Whether you want to integrate with Apache Airflow for orchestration, run exploratory analysis in Jupyter, or leverage ML tools like MLflow for your machine learning pipelines, Ilum supports it all.

With Ilum, you maintain full control to build a data ecosystem that perfectly matches your needs.

Explore our Ecosystem
Kubernetes Native

Kubernetes Native

Leverage the scalability and robustness of Kubernetes without the hassle of manual configuration.
Flexible Storage

Flexible Storage

Connect to build-in S3 based interface or use: Amazon S3, Azure Storage, Google Cloud Storage, HDFS.
Anywhere

Anywhere

Deploy Ilum anywhere — be it on the cloud, on-premise, or a hybrid environment, giving you the ultimate flexibility in deployment.

Managed Spark Cluster on Kubernetes

Tired of the complexity of Hadoop or Cloudera? Ilum delivers the power of Apache Spark and Airflow without the headache, offering a seamless cloud-native data platform alternative.


Managing a Spark Cluster can be challenging, but Ilum makes it straightforward. We handle the hard part of Kubernetes Spark operator management, allowing you to focus on extracting insights from your data.

With Kubernetes at its core, Ilum automates spark cluster provisioning, scales resources dynamically based on workload demands, and ensures high availability for your big data workloads.


Ilum is not just a platform for managing and monitoring Apache Spark on Kubernetes. It also serves as your own fully managed Spark cluster and Data Lakehouse.
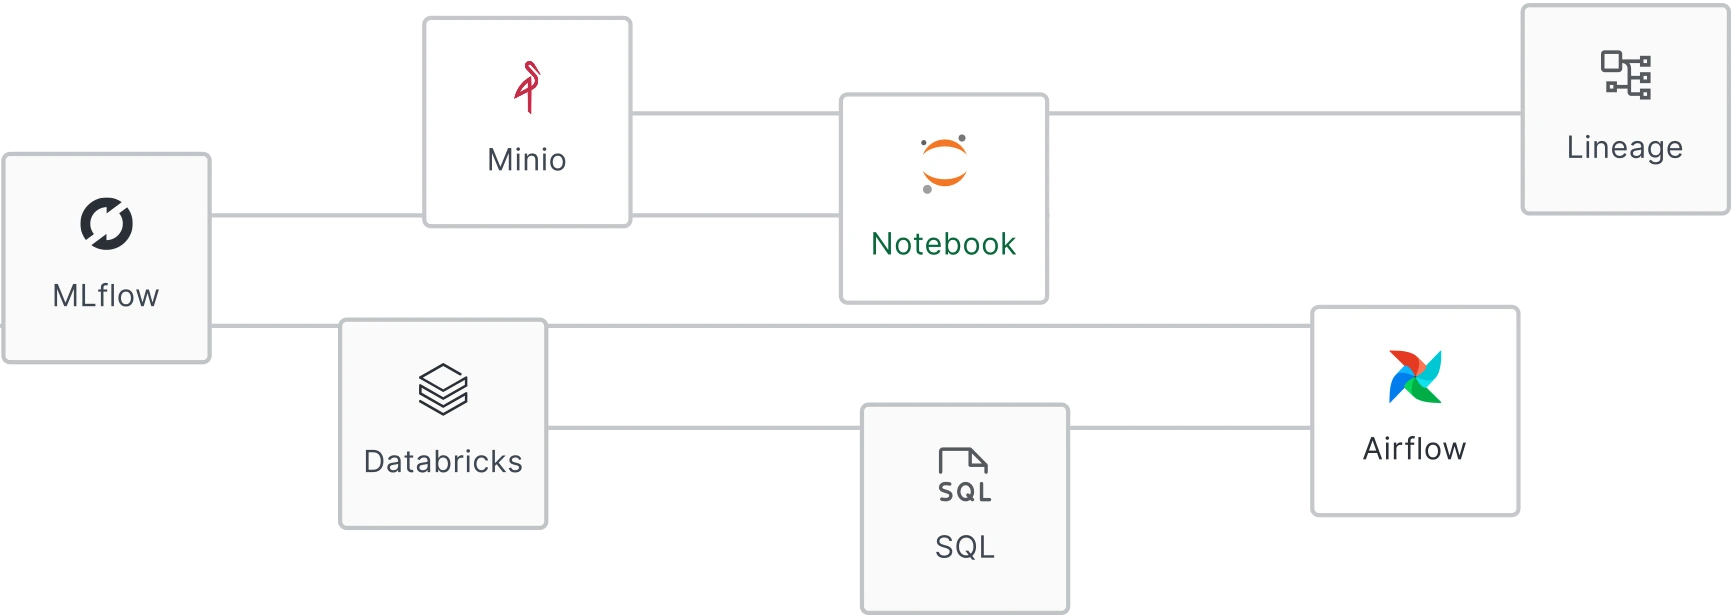
Ilum Data Lakehouse Tech Stack showing Apache Spark, Kubernetes and Airflow

Observability at your hands

Eliminate the guesswork in debugging with Ilum’s detailed logs and metrics. Easily dive into Spark logs and performance metrics, all in one place, making it simpler to identify bottlenecks and issues that are often hard to trace in standard environments.

Debugging and Monitoring with Ilum

Ilum provides a unified environment for monitoring your Spark jobs through detailed logs and performance metrics. While traditional environments make it challenging to access logs and metrics in one place, Ilum simplifies this process, allowing developers to dive deep into Spark logs and metrics without switching between multiple tools.

By offering centralized access to key logs and real-time performance metrics, developers can quickly pinpoint bottlenecks, trace errors, and optimize Spark jobs. It provides the essential insights needed to resolve issues faster and improve cluster performance.

This streamlined approach improves productivity by keeping vital monitoring resources at your fingertips, making it easier to manage and troubleshoot your Spark environment.

Get it for free

Technologies used in ilum

Have some ideas how to improve Ilum?

We value your feedback and are always eager to improve. If you have suggestions that could enhance your experience or make navigating the product easier, please let us know. Join us in shaping the future of our platform! Your input matters.

Add feature request

Interactive Sessions aka Spark Microservices

Eliminate up to 99% of the time that would normally be spent on an initialization of spark job.
Control a Spark Session over REST API and build a real-time interaction with a Spark Cluster.

SparkPi with spark-submit on yarn 50 seconds

Interactive SparkPi with Ilum API on kubernetes 1 second

No matter if your Spark setup
uses Hadoop Yarn or Kubernetes

Multi-Environment Deployment

Ilum supports deployment across both cloud and on-premises environments, offering flexibility to run Spark clusters anywhere your infrastructure demands.

Migration Support

Easily transition from legacy systems like Hadoop to modern, cloud-native architectures with Ilum’s built-in migration capabilities, minimizing downtime and complexity.

Kubernetes and Hadoop Yarn Integration

Whether you're using Kubernetes for container orchestration or Hadoop Yarn for resource management, Ilum seamlessly integrates with both, ensuring smooth operations in any setup.

Compatibility and Flexibility

Ilum is designed to be adaptable, offering compatibility with various storage systems and tools, ensuring your Spark clusters run efficiently no matter your tech stack.

Play Ilum Product Demo Video

We can help you make a good start

How to run Apache Spark on Kubernetes in less than 5min

How to run Apache Spark on Kubernetes in less than 5min

Tools like Ilum will go a long way in simplifying the process of installing Apache Spark on Kubernetes...

Read article
Deploying PySpark Microservice on Kubernetes: Revolutionizing Data Lakes with Ilum.

Deploying PySpark Microservice on Kubernetes: Revolutionizing Data Lakes with Ilum.

Greetings Ilum enthusiasts and Python fans! We're thrilled to unveil a new, eagerly expected feature that's set to empower...

Read article
What is a Data Lakehouse?

What is a Data Lakehouse?

Explore the concept of the data lakehouse, a modern approach to data management that combines the benefits of ...

Read article
How to optimize your Spark Cluster with Interactive Spark Jobs

How to optimize your Spark Cluster with Interactive Spark Jobs

There are three types of jobs you can run in Ilum: single job, interactive job and interactive code...

Read article
How to run Apache Spark on Kubernetes in less than 5min

How to run Apache Spark on Kubernetes in less than 5min

Tools like Ilum will go a long way in simplifying the process of installing Apache Spark on Kubernetes...

Read article
Deploying PySpark Microservice on Kubernetes: Revolutionizing Data Lakes with Ilum.

Deploying PySpark Microservice on Kubernetes: Revolutionizing Data Lakes with Ilum.

Greetings Ilum enthusiasts and Python fans! We're thrilled to unveil a new, eagerly expected feature that's set to empower...

Read article
What is a Data Lakehouse?

What is a Data Lakehouse?

Explore the concept of the data lakehouse, a modern approach to data management that combines the benefits of ...

Read article
How to optimize your Spark Cluster with Interactive Spark Jobs

How to optimize your Spark Cluster with Interactive Spark Jobs

There are three types of jobs you can run in Ilum: single job, interactive job and interactive code...

Read article
How to run Apache Spark on Kubernetes in less than 5min

How to run Apache Spark on Kubernetes in less than 5min

Tools like Ilum will go a long way in simplifying the process of installing Apache Spark on Kubernetes...

Read article
Deploying PySpark Microservice on Kubernetes: Revolutionizing Data Lakes with Ilum.

Deploying PySpark Microservice on Kubernetes: Revolutionizing Data Lakes with Ilum.

Greetings Ilum enthusiasts and Python fans! We're thrilled to unveil a new, eagerly expected feature that's set to empower...

Read article
What is a Data Lakehouse?

What is a Data Lakehouse?

Explore the concept of the data lakehouse, a modern approach to data management that combines the benefits of ...

Read article
How to optimize your Spark Cluster with Interactive Spark Jobs

How to optimize your Spark Cluster with Interactive Spark Jobs

There are three types of jobs you can run in Ilum: single job, interactive job and interactive code...

Read article
How to run Apache Spark on Kubernetes in less than 5min

How to run Apache Spark on Kubernetes in less than 5min

Tools like Ilum will go a long way in simplifying the process of installing Apache Spark on Kubernetes...

Read article
Deploying PySpark Microservice on Kubernetes: Revolutionizing Data Lakes with Ilum.

Deploying PySpark Microservice on Kubernetes: Revolutionizing Data Lakes with Ilum.

Greetings Ilum enthusiasts and Python fans! We're thrilled to unveil a new, eagerly expected feature that's set to empower...

Read article
What is a Data Lakehouse?

What is a Data Lakehouse?

Explore the concept of the data lakehouse, a modern approach to data management that combines the benefits of ...

Read article
How to optimize your Spark Cluster with Interactive Spark Jobs

How to optimize your Spark Cluster with Interactive Spark Jobs

There are three types of jobs you can run in Ilum: single job, interactive job and interactive code...

Read article
PreviousNext

Frequently Asked Questions

What is a Data Lakehouse?

Expand

A Data Lakehouse is a new, open data management architecture that combines the flexibility, cost-efficiency, and scale of data lakes with the data management and ACID transactions of data warehouses, enabling business intelligence (BI) and machine learning (ML) on all data.

How does Ilum simplify Spark on Kubernetes?

Expand

Ilum abstracts the complexity of managing Apache Spark on Kubernetes. It provides a managed control plane that handles cluster provisioning, auto-scaling, and lifecycle management, allowing you to focus on your data and code rather than infrastructure.

What makes Ilum a Modern Data Platform?

Expand

Ilum is a Modern Data Platform because it unifies data lakes and warehouses into a single architecture (Data Lakehouse). It is cloud-native, built on Kubernetes, and supports a wide ecosystem of tools (Spark, Airflow, MLflow), giving you the flexibility and scalability needed for modern data workloads.

Is Ilum really free?

Expand

Yes! Ilum offers a free version that gives you access to the core Data Lakehouse platform. You can deploy it on your own infrastructure (on-premise or cloud) without any licensing fees for the core features.

Can I use Ilum with my existing tools?

Expand

Absolutely. Ilum is built on open standards and integrates seamlessly with popular tools like Jupyter Notebooks, Apache Airflow, and MLflow. It also supports various storage backends including S3, GCS, Azure Blob Storage, and HDFS.

How does Ilum compare to Databricks?

Expand

While Databricks is a powerful commercial platform, Ilum offers a lightweight, flexible, and cost-effective alternative that you can host yourself. Ilum provides a similar unified experience for Spark, Airflow, and MLflow but gives you full control over your infrastructure and data sovereignty.

Contact us

We're here to help. Reach out to us today.

Email Icon[email protected]
Accept Terms Checkbox

I accept the Privacy Policy

Ilum Logo

Optimize Data Operations with Unmatched Speed and Control.

Get Started